E2E Multi-Stage Intelligent Financial Data Extraction System
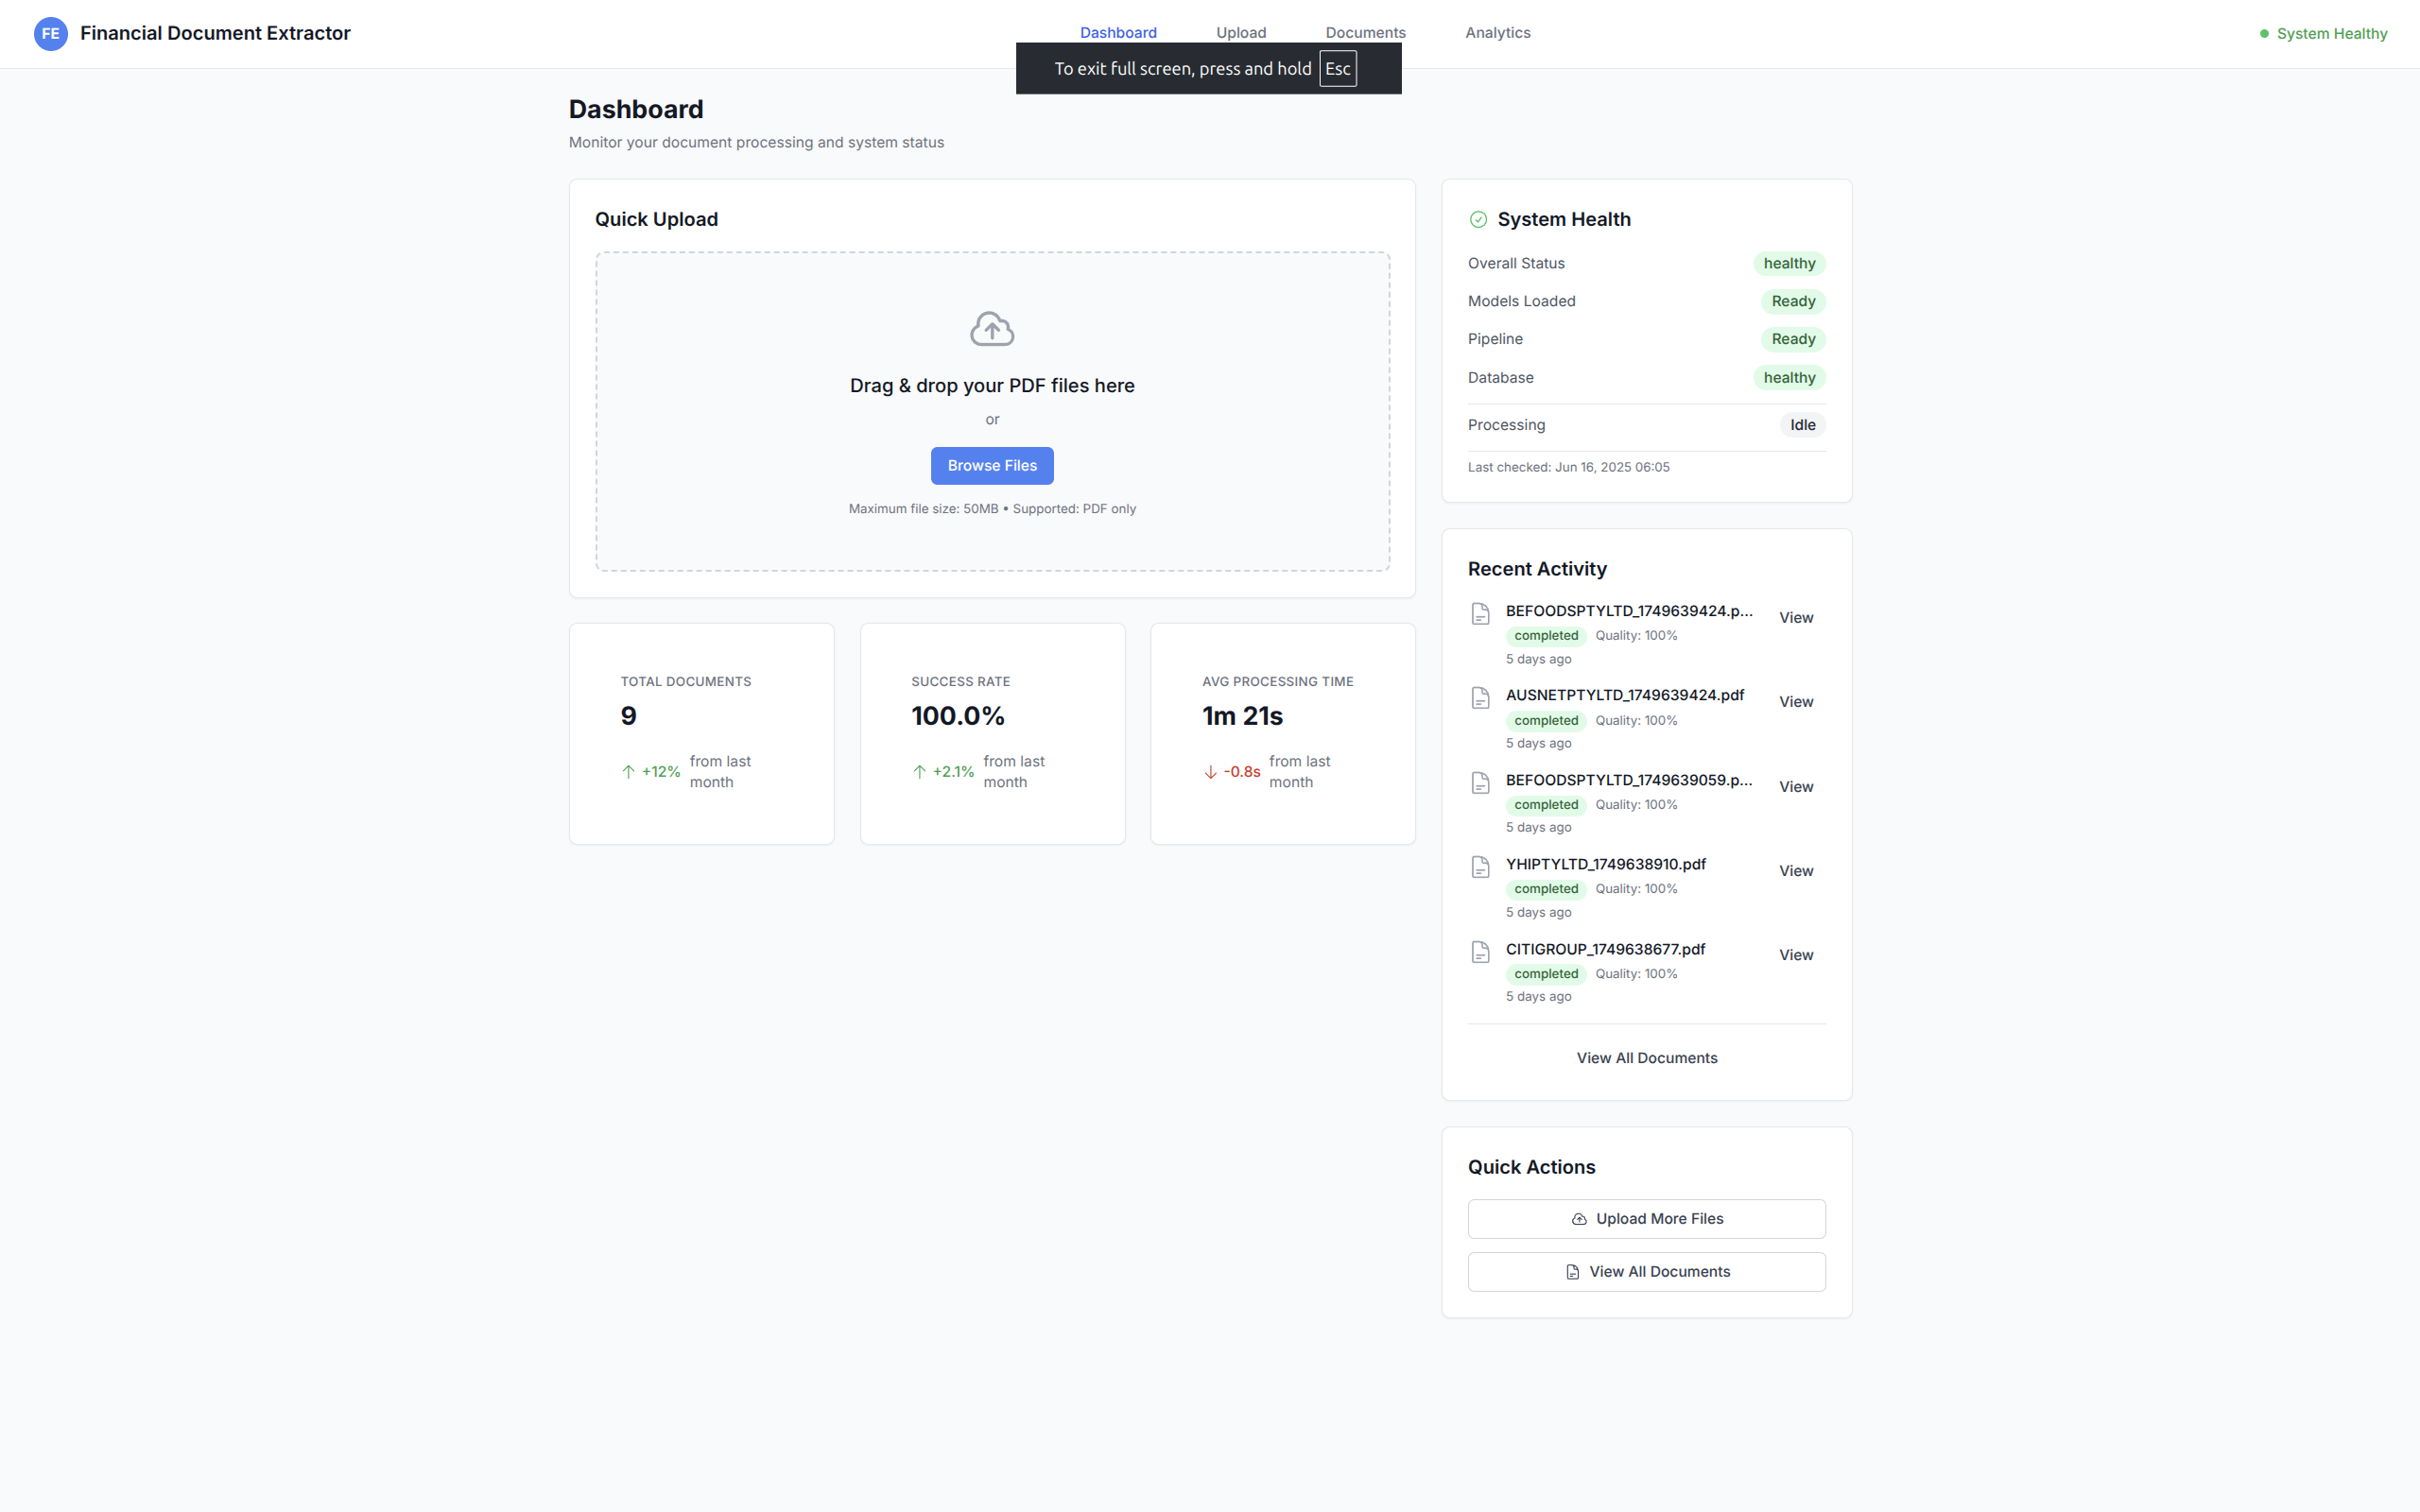
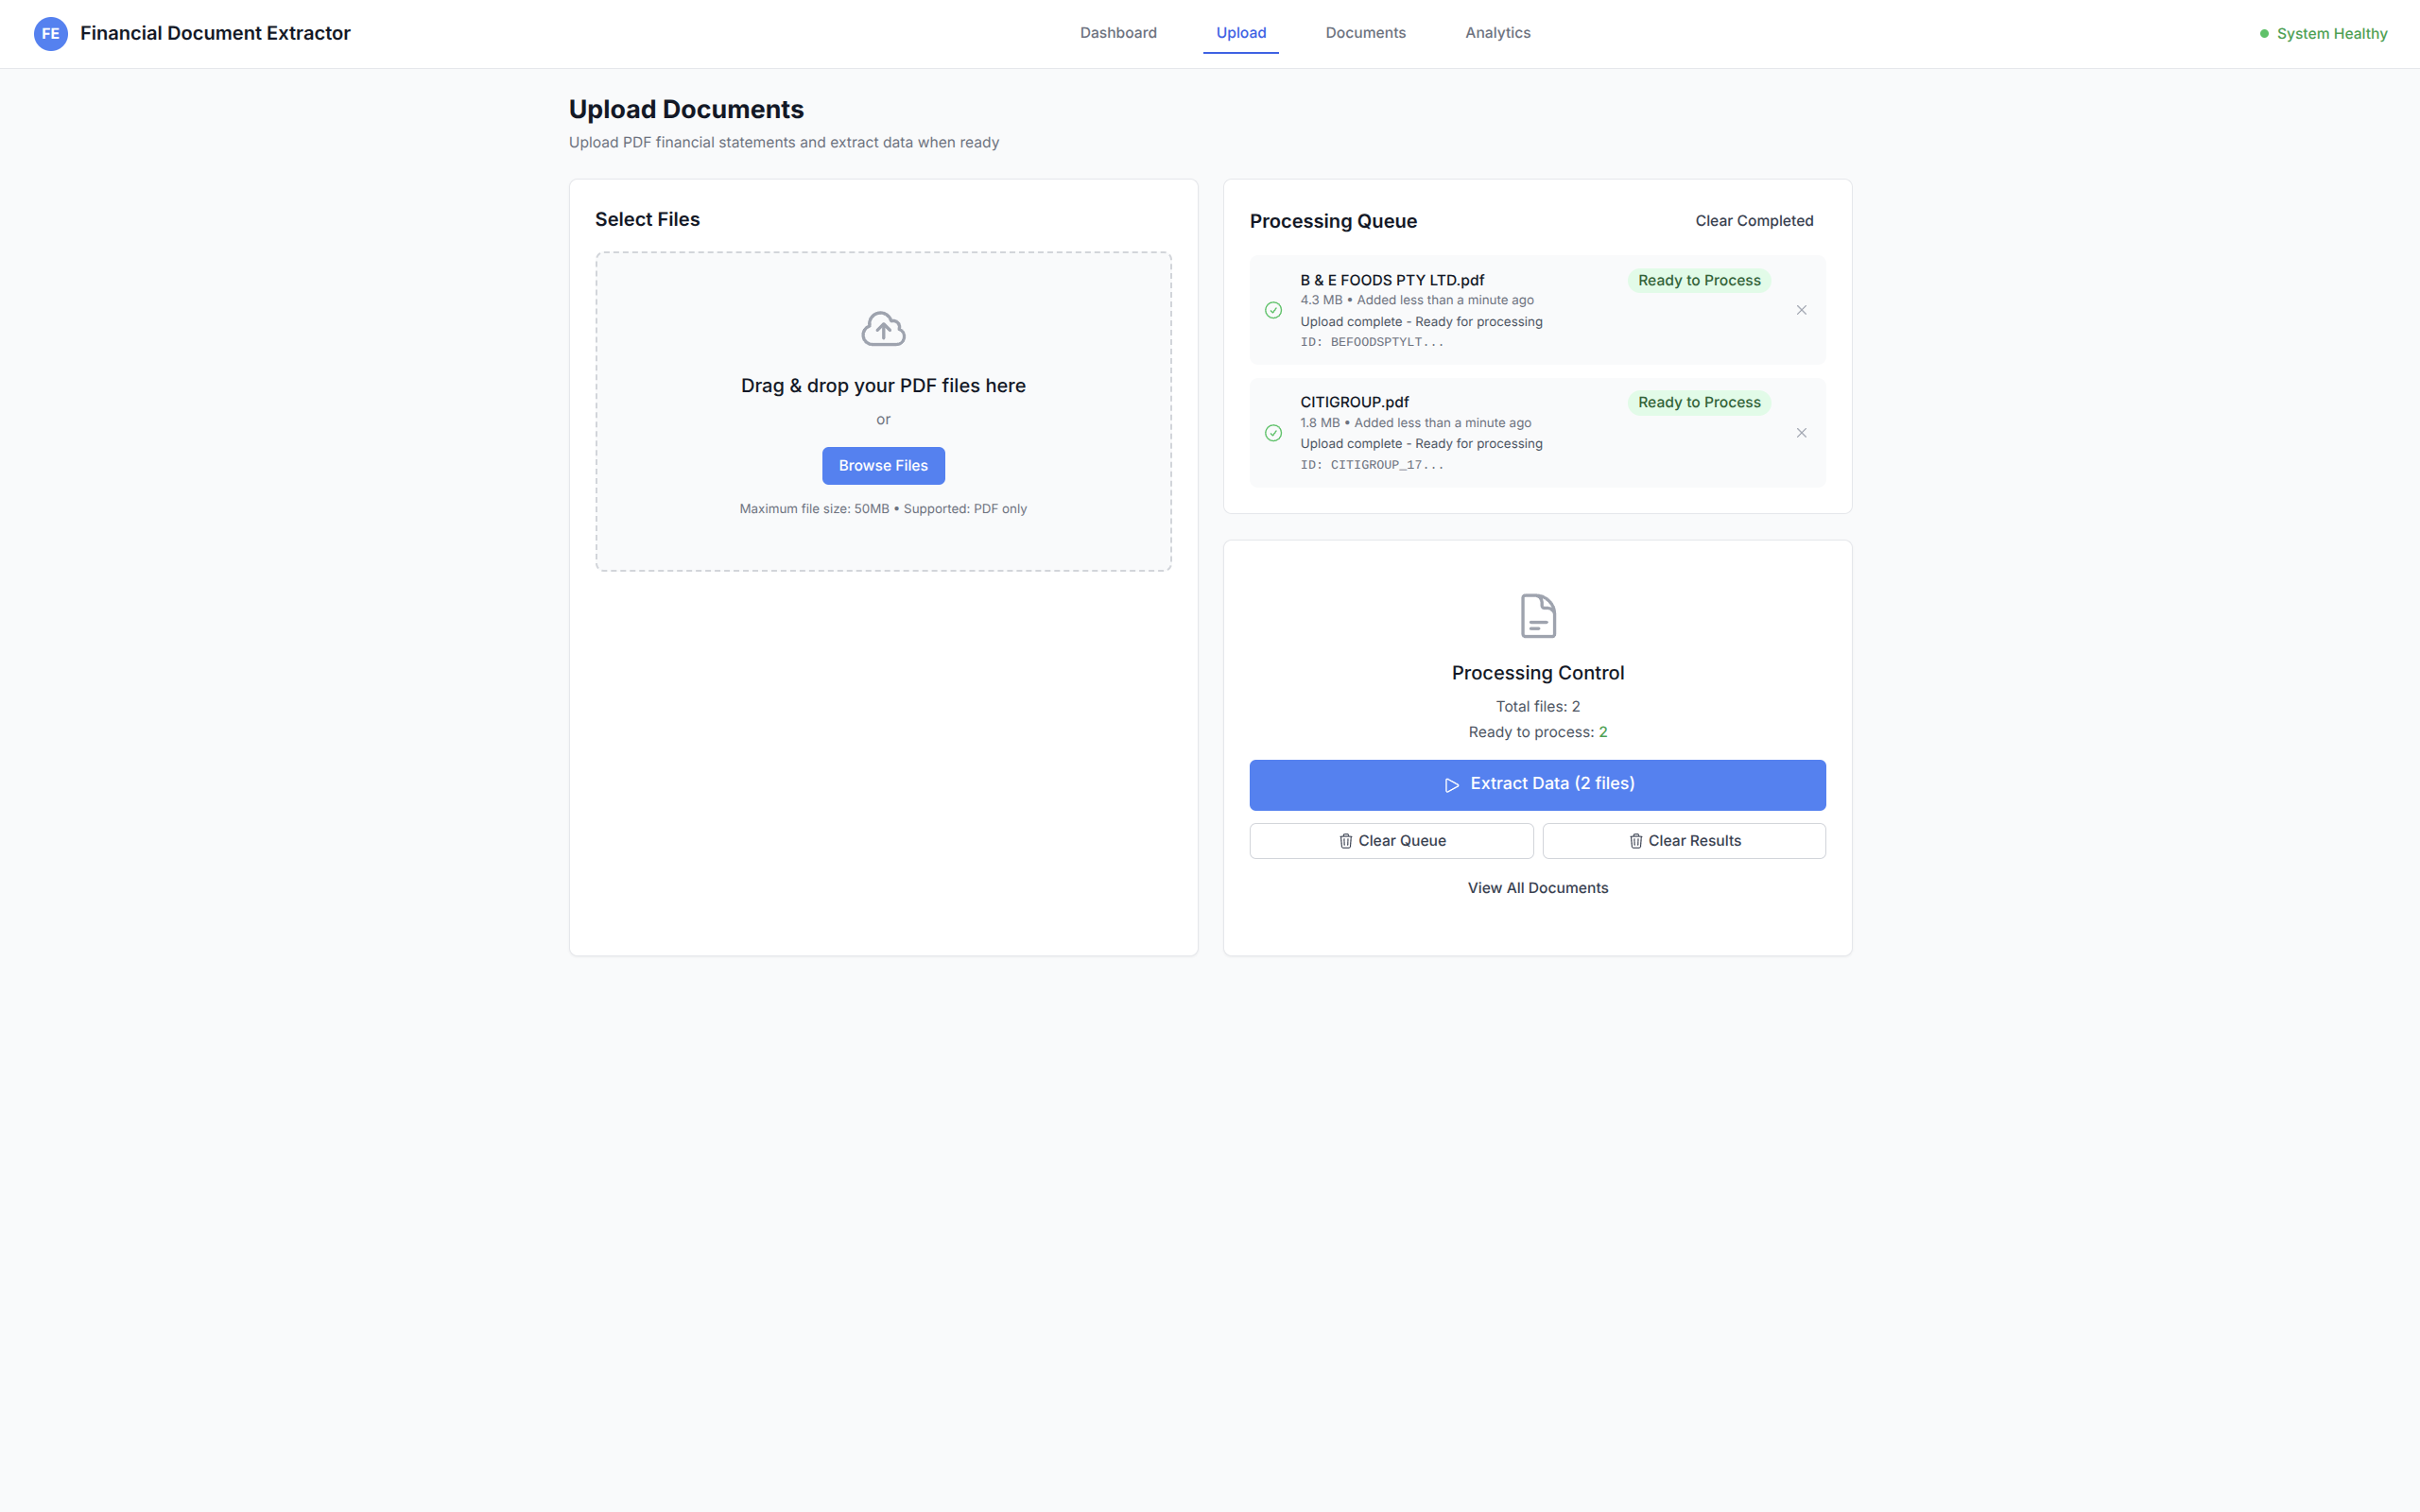
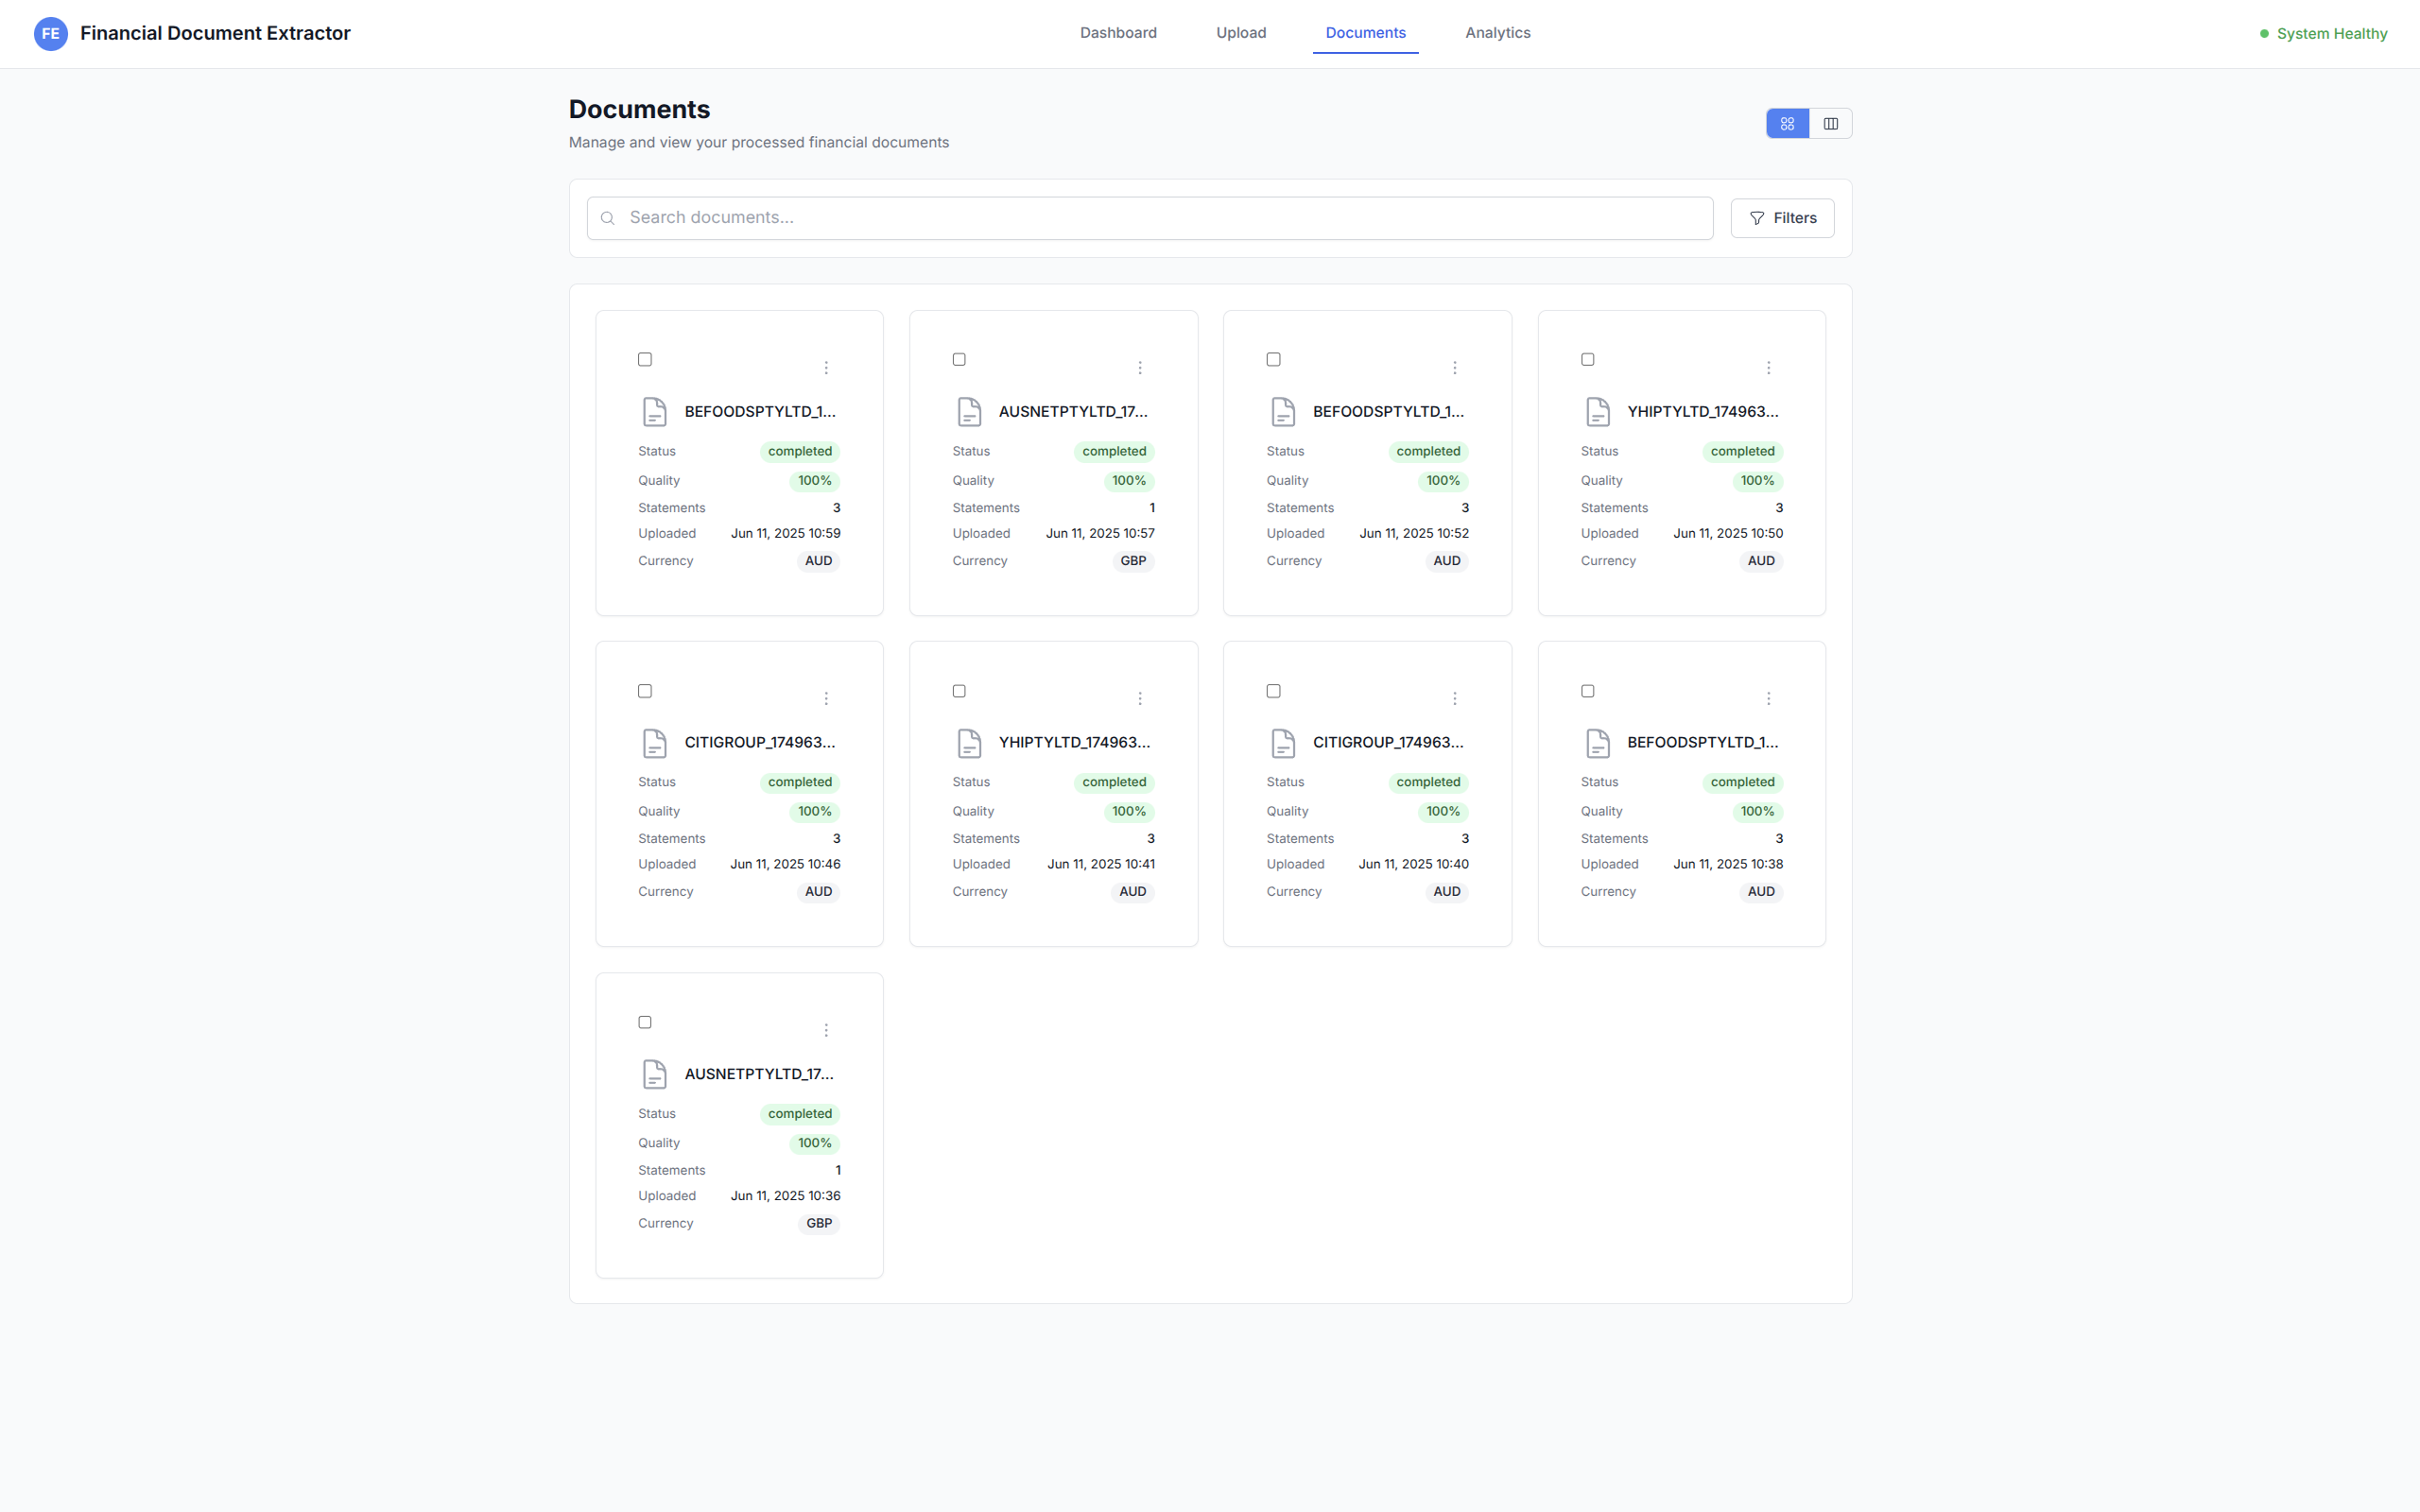
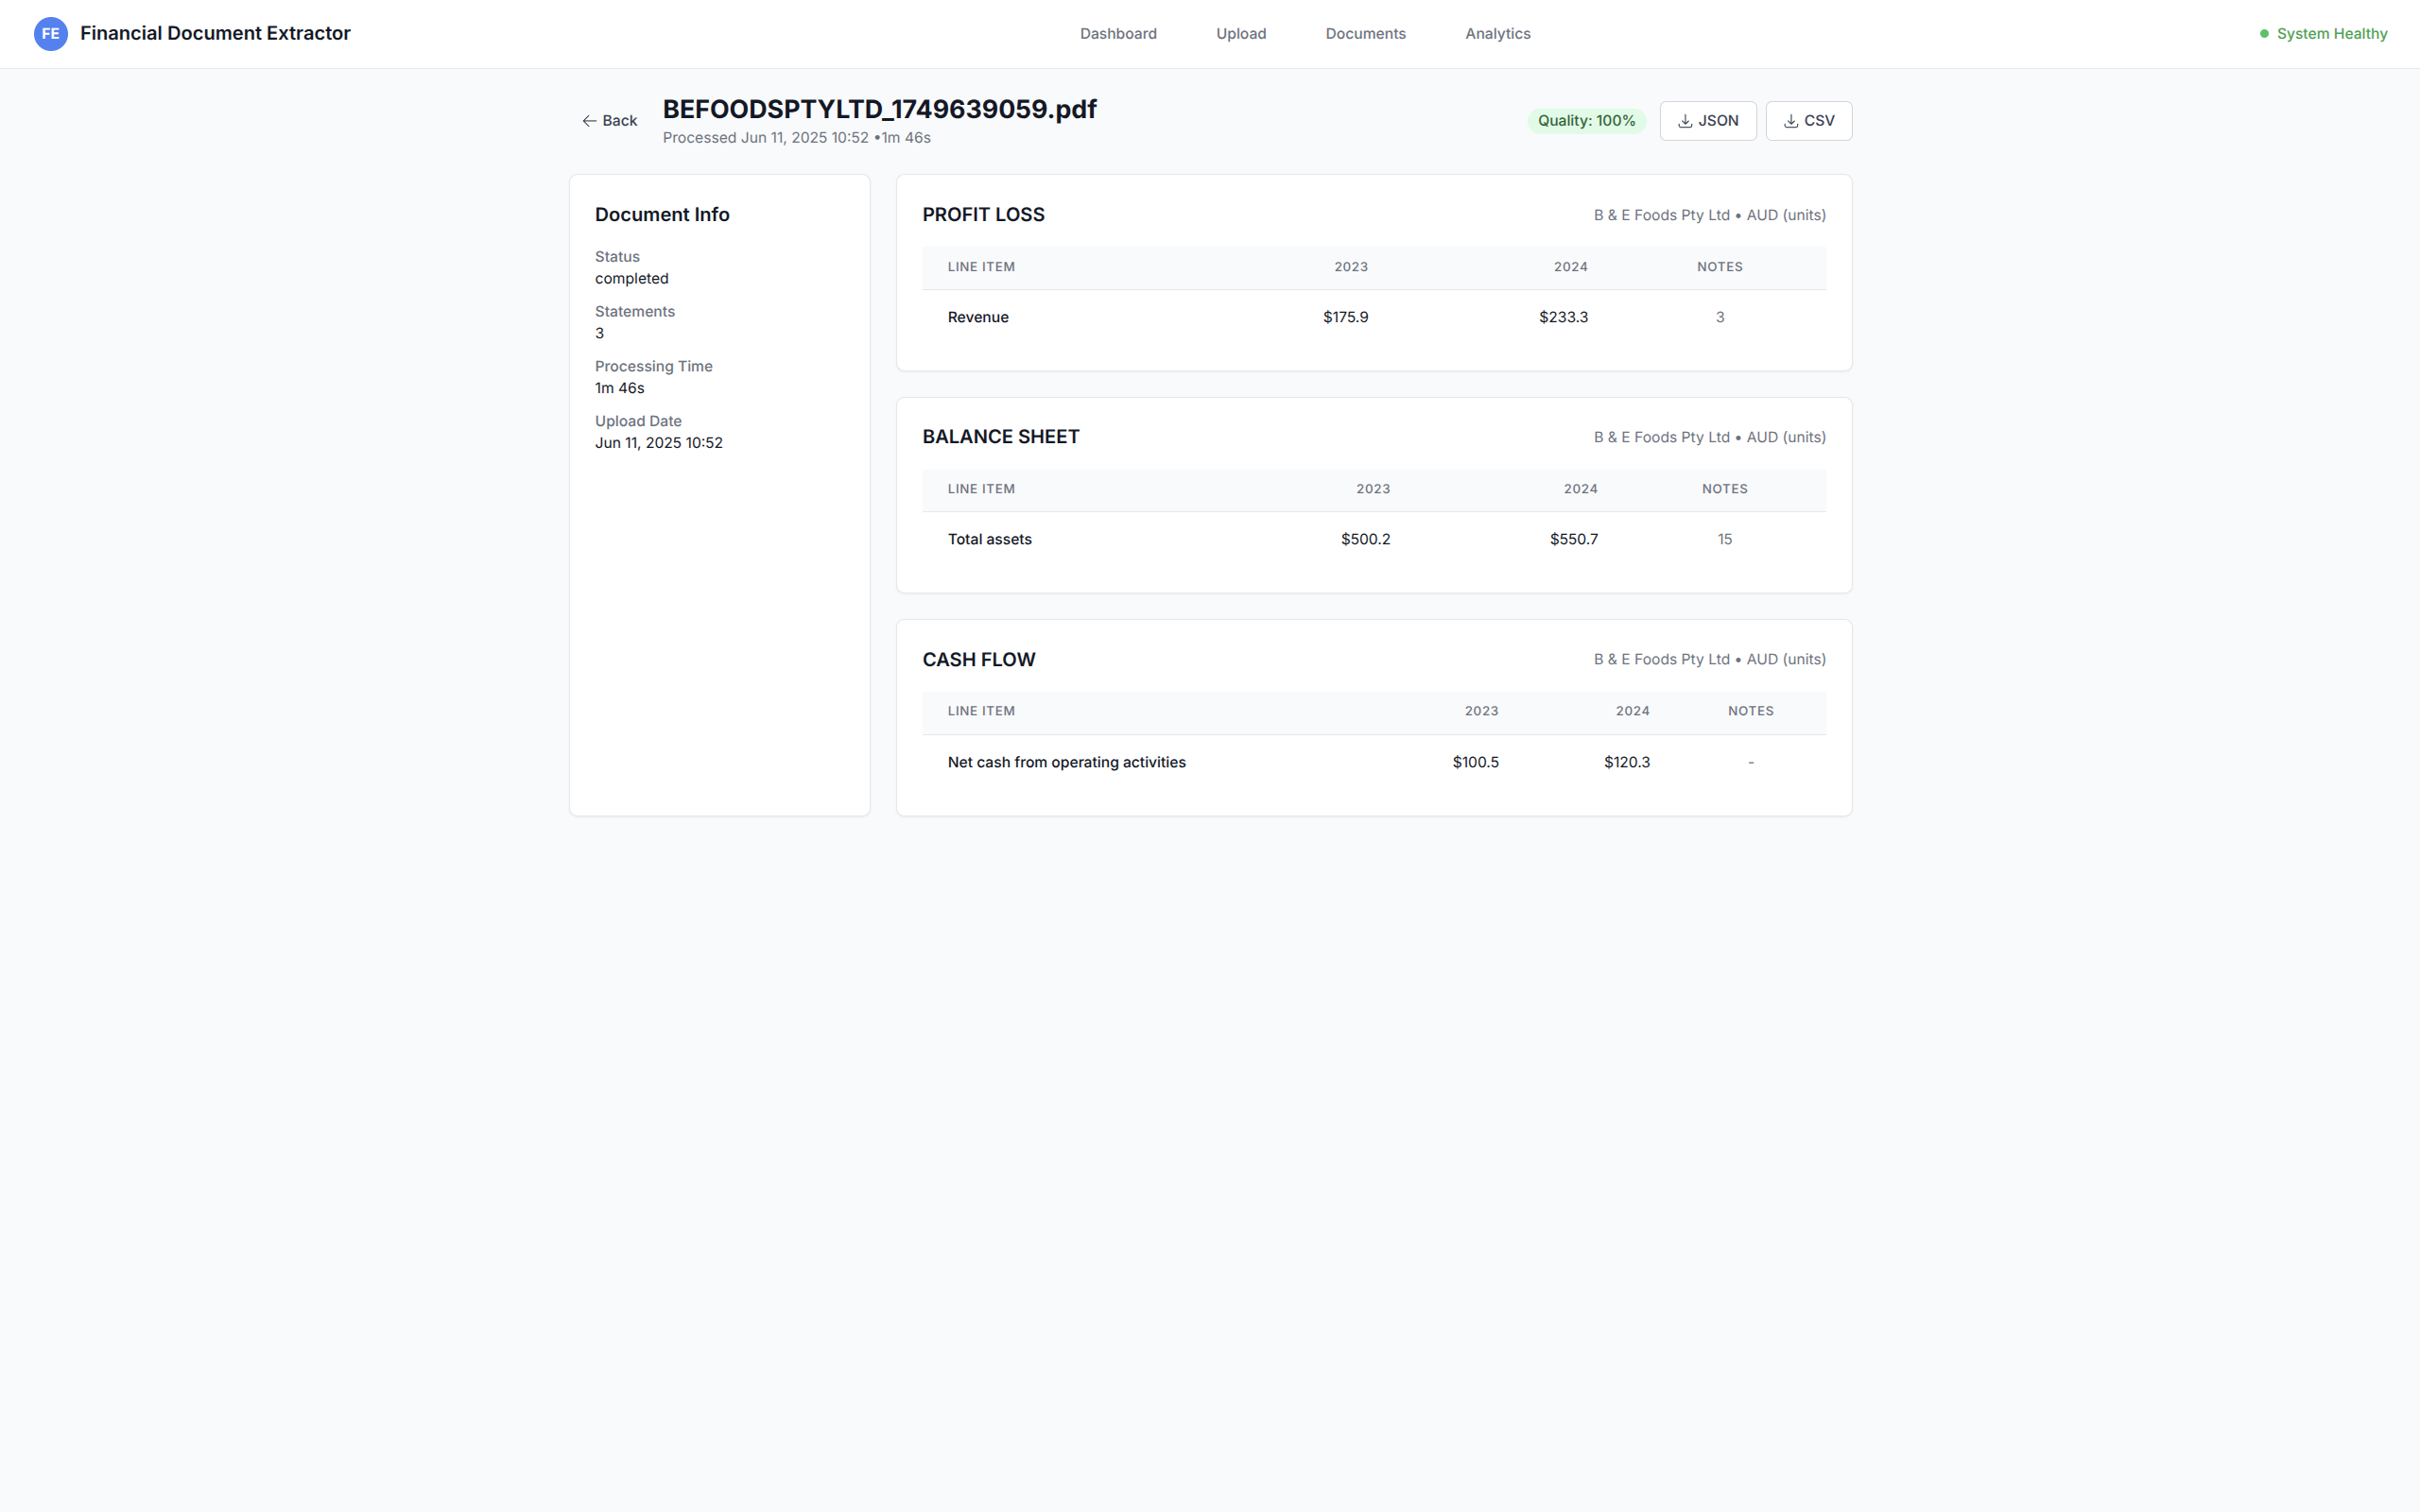
View on GitHubFastAPI and React pipeline turning messy financial PDFs into validated structured data, entirely offline. A three-tier adaptive LLM fallback preserves line items and their note references instead of flattening them.
Manual extraction from annual reports and financial statements is slow, error-prone, and especially fragile when note references, rounding, and currency metadata matter. Plain OCR loses layout context, and naive LLM extraction can hallucinate structure or drop the relationship between a line item and its note. The goal was a local-first application that turns messy financial PDFs into validated structured data without sensitive documents ever leaving the machine.
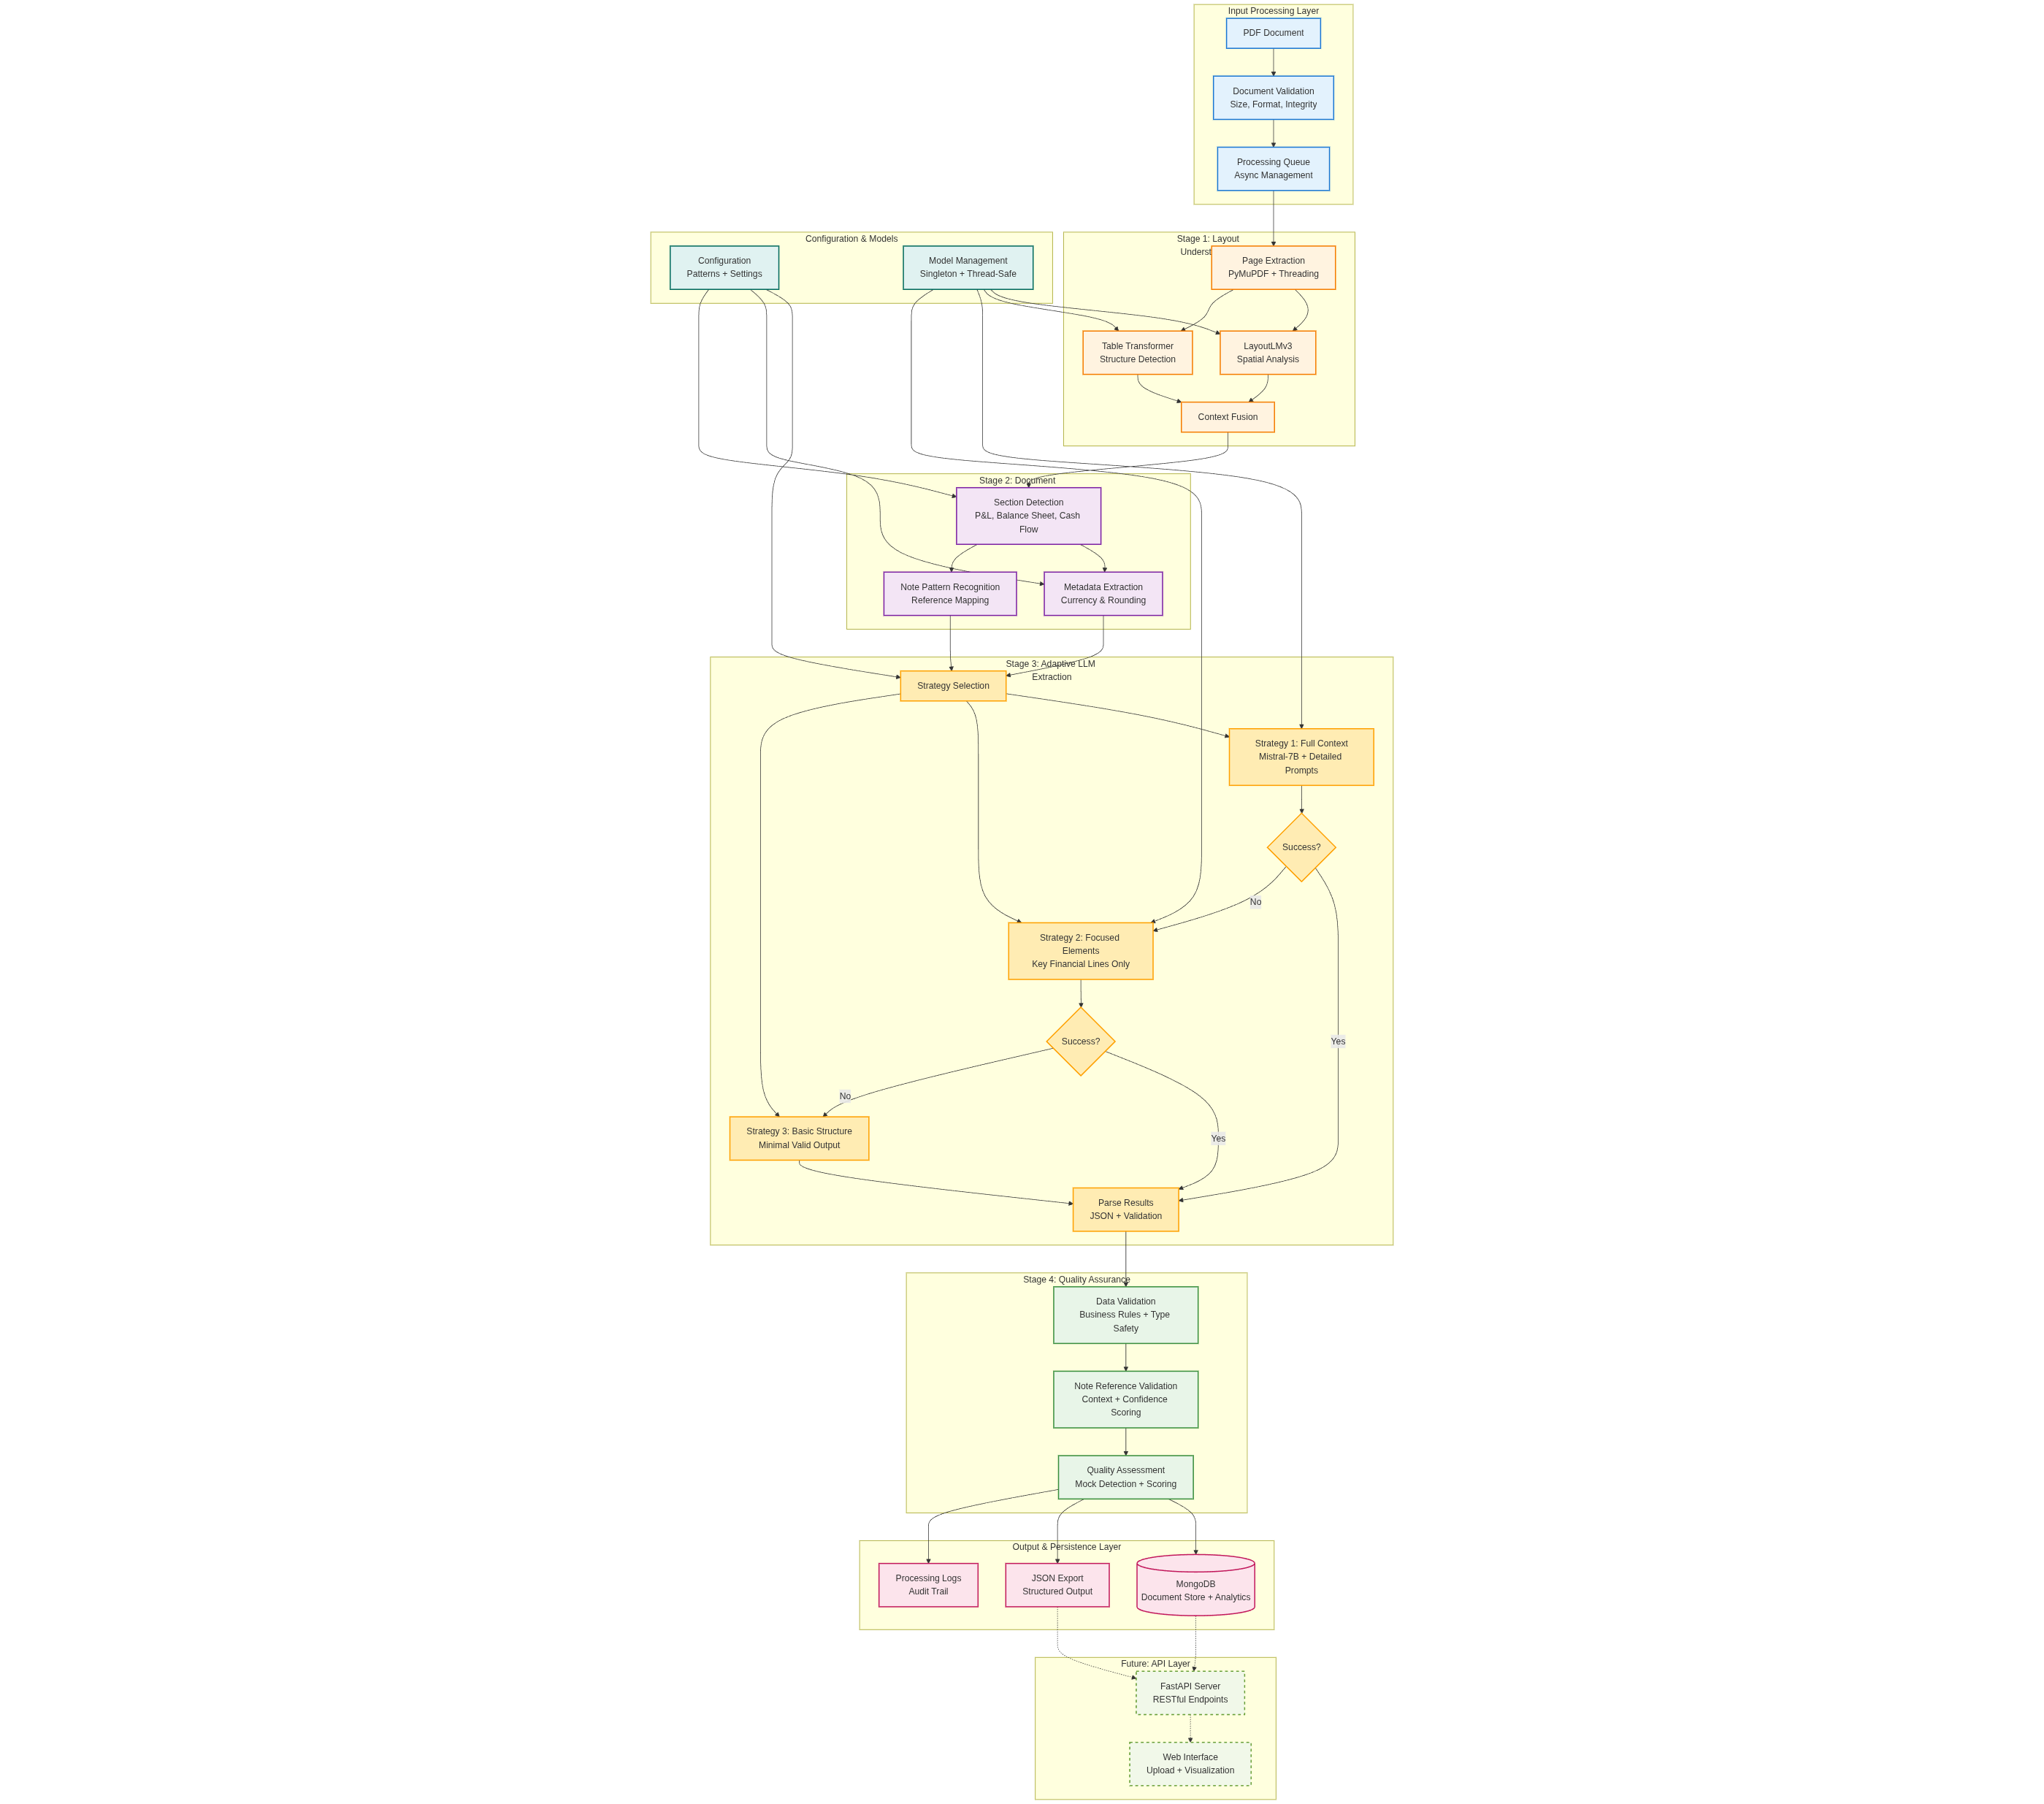
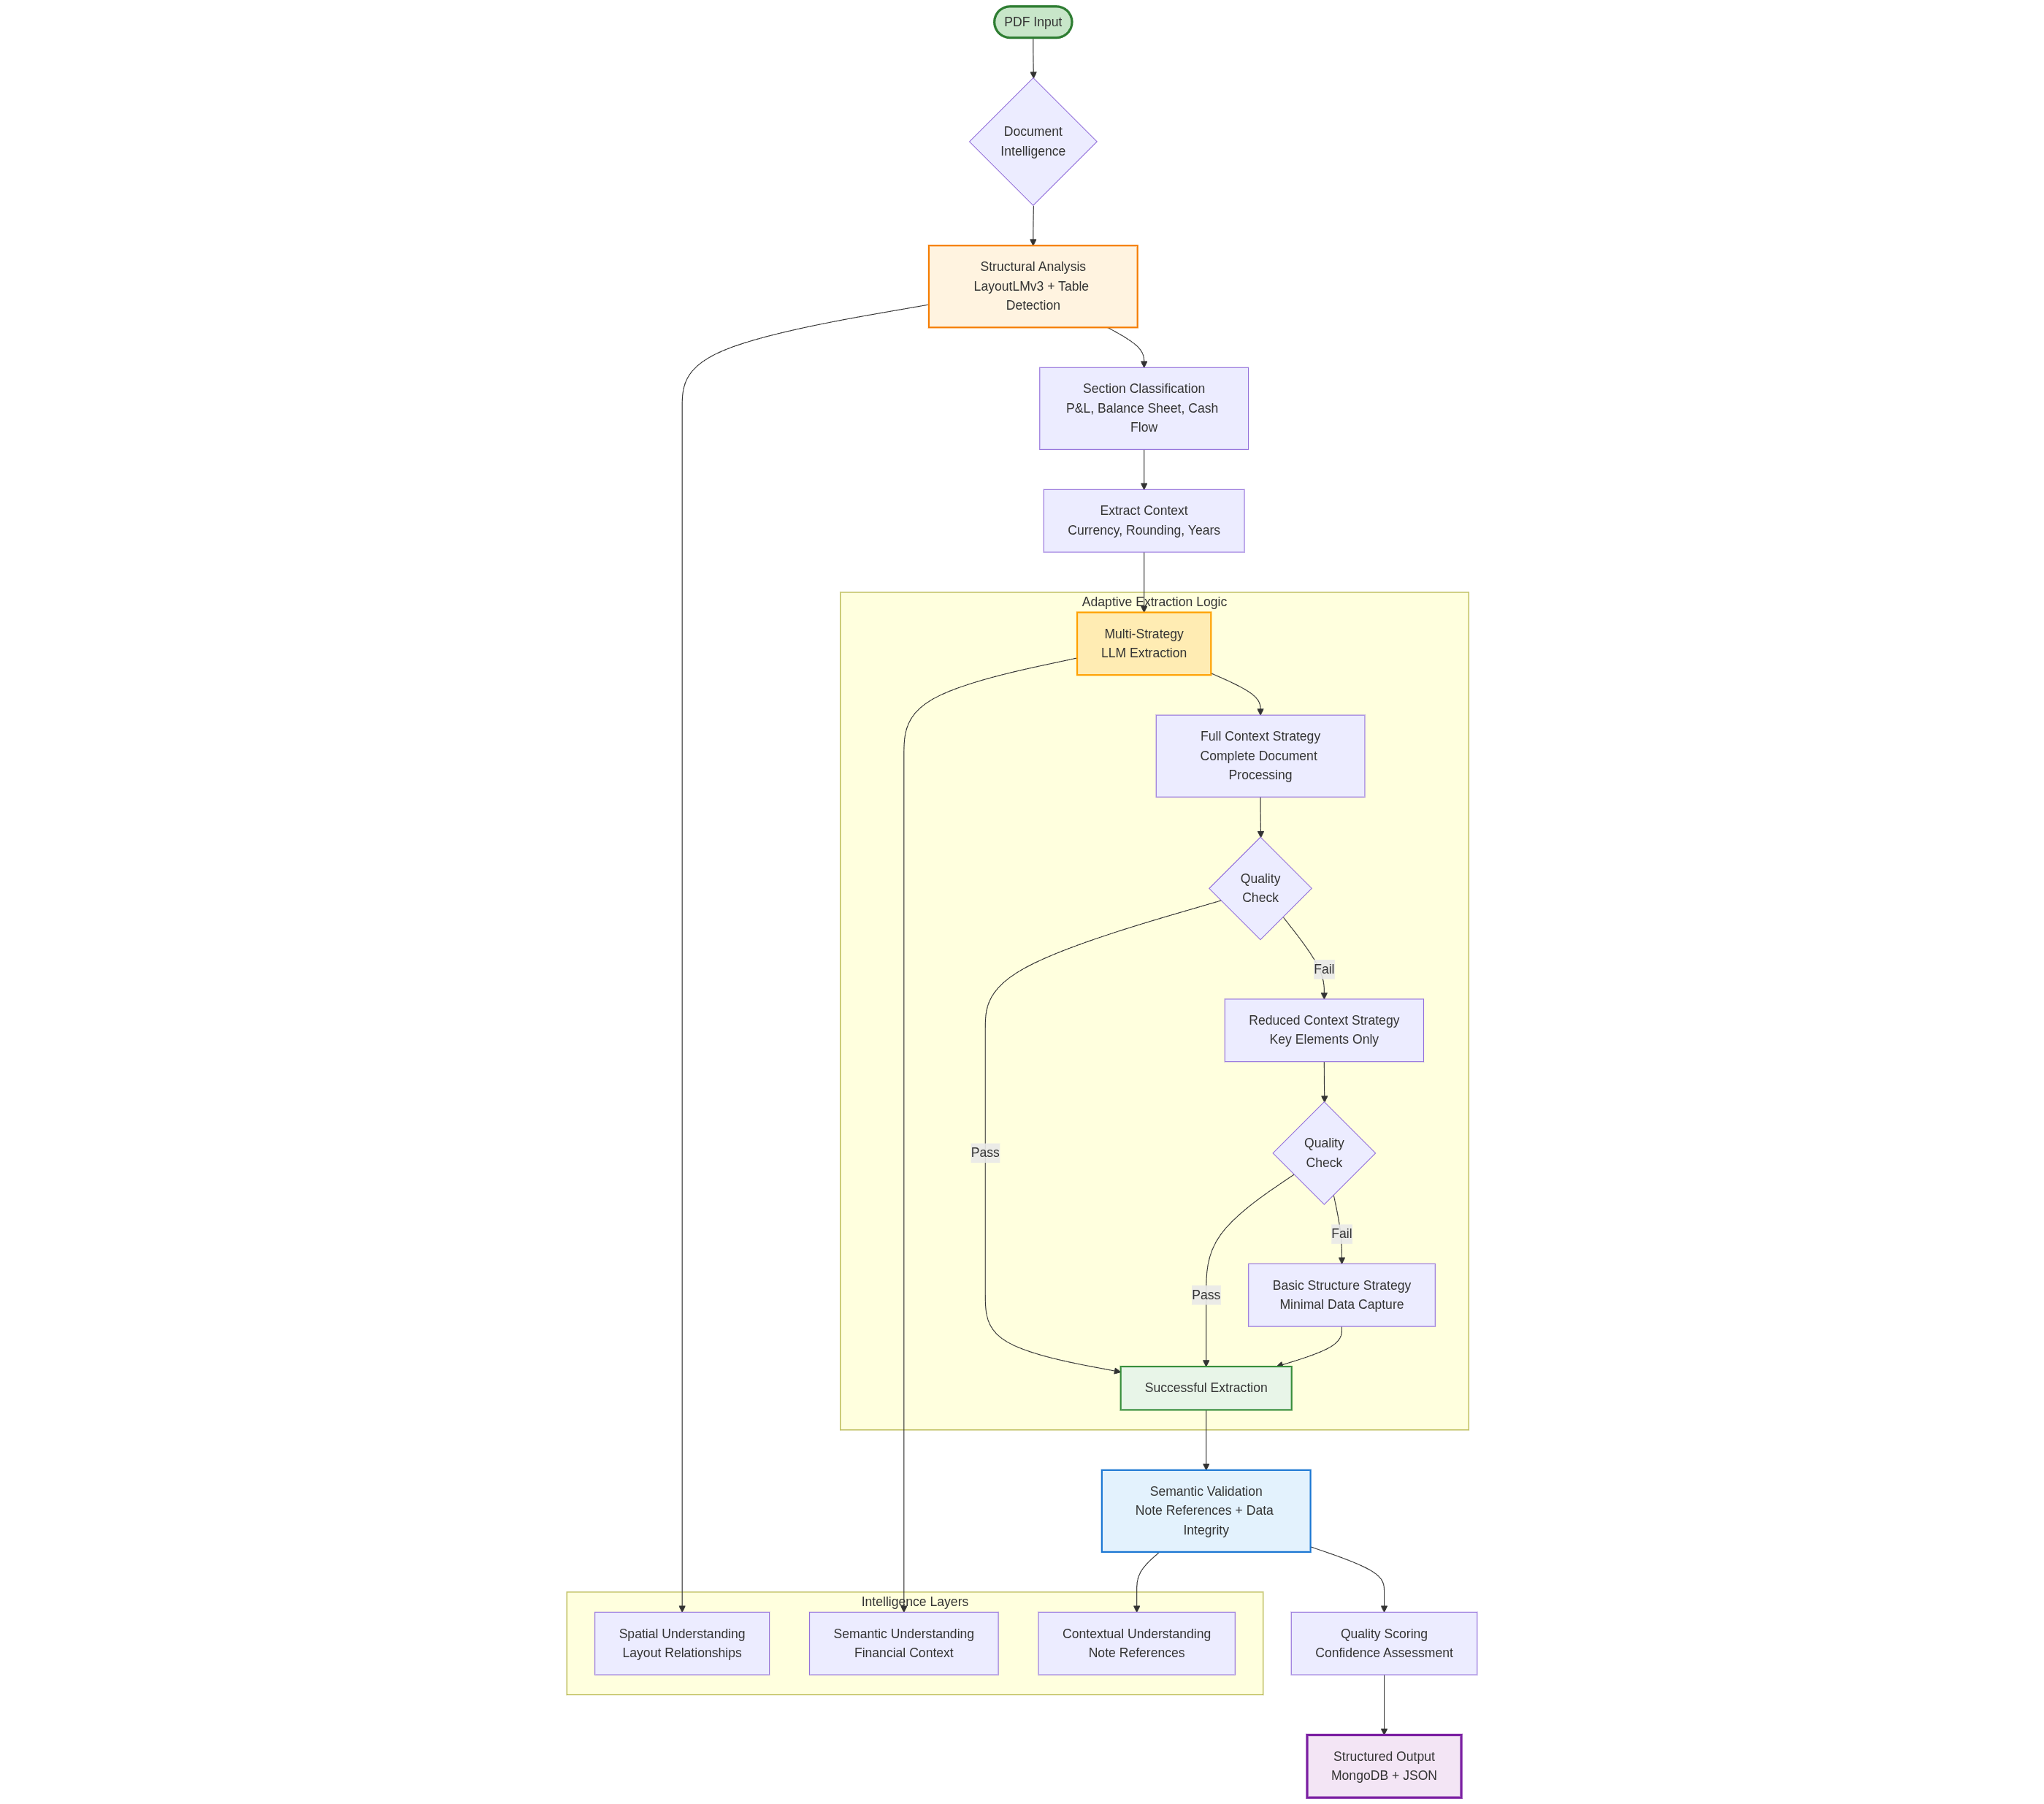
The system splits into a FastAPI backend, a React and TypeScript frontend, a MongoDB persistence layer, and a Python processing pipeline. A PDF processor uses PyMuPDF for text extraction alongside LayoutLMv3 and Table Transformer for layout-aware analysis before any language model sees the content. Extraction runs on a locally hosted Mistral-7B model through llama.cpp with a three-tier fallback strategy, full line-by-line extraction first, then a reduced-context pass, then a basic-structure fallback, so a noisy or partially parsed document still produces usable output. Currency and rounding are inferred from the document itself and cross-checked against extracted statements to catch mismatches early, and the pipeline rejects suspicious mock-like values before saving. Everything runs offline, which fits sensitive financial documents better than sending them to an external API.